Keyword plus vector search
Mean reciprocal rank on 127 keyword-style queries. Higher is better.
- Before
- 0.748
- After
- 0.823
0.851 with the Hybrid reranker; on 125 paraphrased questions the change was within noise.
Ask your documents on your own machine, and check every answer against the exact file and page it came from.
What is the total cost, and when is delivery?
ParsRAG2 sources
The total cost is 4.2 billion rials, including licenses and three months of support. Delivery is planned for the end of Azar 1405, after the acceptance test.
Ask about these documents, or @ one of them
PDFbudget.pdfpage 3
The total project cost is 4.2 billion rials, including licenses and three months of support.
DOCXtimeline.docxparagraph 7
Delivery is planned for the end of Azar 1405, after the acceptance test passes.
Inside the app
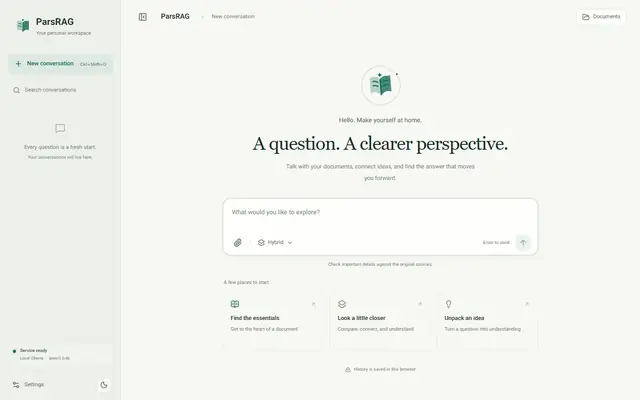
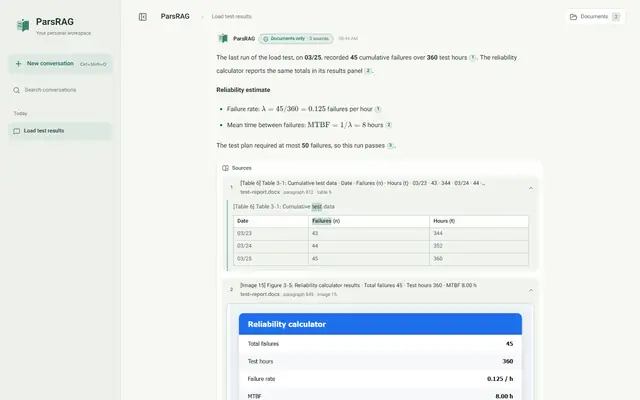
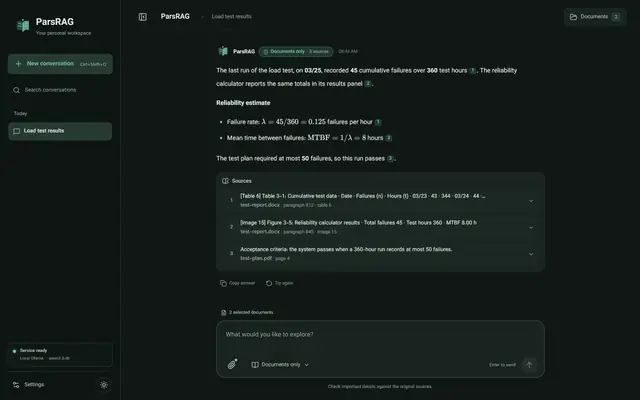
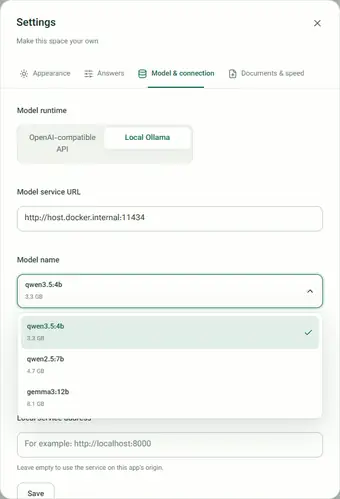
Screens from the ParsRAG repository: the workspace, cited sources and model settings, in light and dark.
See every screen in the tour02Documents-only mode
In Documents only mode, a sentence stays in the answer only while a passage supports it. Take the passage away and the claim goes with it.
Strict mode answers by meaning, so paraphrased and whole-document questions still work, but every fact has to come from your documents.
Rent is 45 million rials a month, due by the 5th.
The provided documents do not answer this question.
The monthly rent is 45 million rials, payable by the 5th day of each month.
PDF lease.pdf, page 1
Supported by one passage
03Under the hood
From upload to cited answer, every step that touches your document runs on your machine.
04Privacy
Reading, OCR, the search index and your conversations stay local. Only the model you choose decides where the answer is written.
Generation runs on this workstation. No prompt or excerpt leaves through the model adapter.
A typical cloud chatbot does all five on the provider's servers. API keys stay in memory or environment variables, never in browser storage, logs or API responses.
05Measured
Every number here links to where the repository records it. We'd rather show a small, honest gain than a big, vague claim.
Mean reciprocal rank on 127 keyword-style queries. Higher is better.
0.851 with the Hybrid reranker; on 125 paraphrased questions the change was within noise.
Character error on Persian pages turned 90 degrees. Lower is better.
Pages skewed 5 degrees went from 0.40 to 0.24; upright pages were unchanged.
Mean character error after the 1.0 OCR changes. Lower is better.
Grayscale at 200 dpi, no contrast stretching, a confidence-based second pass.
Vector-search MRR with E5 query and passage prefixes.
Too small to justify re-indexing everyone's documents, so it stays opt-in.
The retrieval and OCR figures were measured by the maintainer on document sets that aren't published, so they can't be reproduced from the public repository. The CI checks run in the open on every change.
06Formats
Office files, scans, data and code are read with their structure, so a citation can name a slide or a section, not just a file.
.pdf .docx .pptx
Native structured extraction, with OCR for scanned or image-heavy PDF pages and for images inside Word and PowerPoint files.
.png .jpg .jpeg .webp .bmp .tif .tiff
Validated, normalized and read with Persian and English OCR.
.txt .md .markdown .json .csv .tsv .log
UTF-8, UTF-16 or legacy Windows-1256 Persian and Windows-1252 text. JSON is validated and normalized.
.html .htm .xml .yaml .yml .toml .ini .cfg
Visible text from markup, and plain text from configuration files.
.py .js .jsx .ts .tsx .css .sql
Extracted with section metadata, so answers can point into a file.
By default a conversation holds 10 files, each up to 100 MiB, with up to 500 MiB per upload. Office archives are checked for suspicious compression, and unsupported binaries are rejected rather than misread.
07Two languages
Switch the interface language and the whole workspace changes direction, digits and labels. Each answer follows its own language.
Delivery timelineDocuments
When is delivery planned?
Documents only · 1 source
Delivery is planned for the end of Azar 1405, after the acceptance test.1
1timeline.docxparagraph 7
What would you like to explore?Documents only
08Install
You need Docker, Ollama and 8–16 GB of RAM. The recommended setup uses the Ollama already on your computer, with its models and GPU; after the first download it works offline.
Then open http://127.0.0.1:8000. The first start downloads the embedding model and the reranker (about 100 MB) into the model cache.
# Install Ollama from ollama.com, then pull a model
ollama pull qwen2.5:7b
# Get the code
git clone https://github.com/Pooria82/ParsRAG.git
cd ParsRAG
# Create your settings file
cp .env.example .env
# Set LLM_MODEL_NAME in .env to the model you pulled
# Build and start ParsRAG
docker compose up -d --build
Support the project
ParsRAG is an independent project. A star on GitHub helps people who work with Persian documents find it, and shows which direction is worth building on.
ParsRAG is for people who can't send their files to a cloud chatbot and still want answers they can check.