Guide
Connect a model
ParsRAG writes answers with a model you choose. The choice decides where generation happens and what leaves your machine; reading, OCR and search stay local either way.
| Provider | Where the answer is written | What leaves ParsRAG |
|---|---|---|
| Local Ollama | This workstation | Nothing through the model adapter |
| Private API | A server you control | Your question and the retrieved excerpts |
| External API | A third-party service | Your question and the retrieved excerpts |
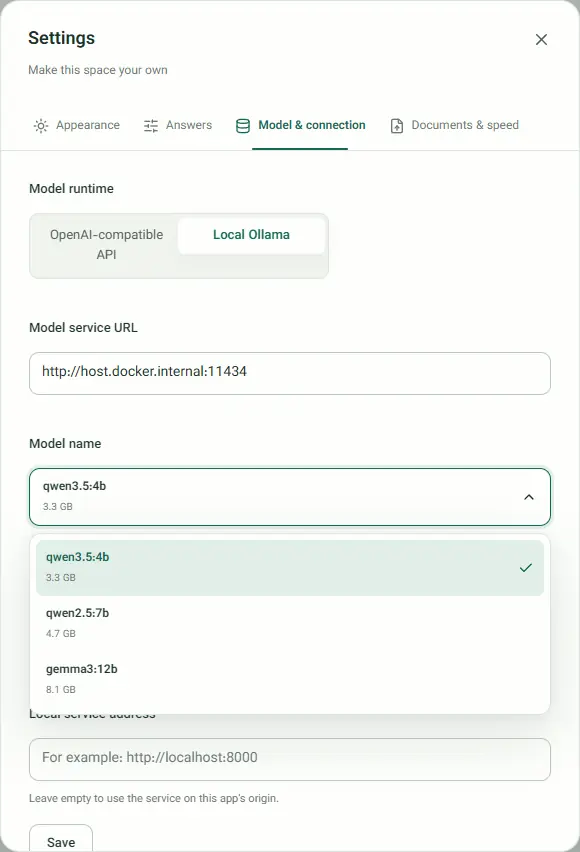
Settings: Model & connection
- Model runtime: OpenAI-compatible API or Local Ollama. A change applies to the next question without a restart.
- For Ollama, the address defaults to http://host.docker.internal:11434, and Find installed models offers the installed models in a menu with their sizes.
- API key: held only in the service's memory, never in the browser or the configuration file. After a restart, enter it again or provide it as an environment variable.
- API privacy boundary: before an external API can be used, you confirm that your question and relevant passages will be sent to it.
- The connection is checked before the non-secret settings are saved. When Ollama fails, Settings says why (the address isn't allowed, or Ollama didn't answer), and when an API is active it offers the server's own Ollama URL.
- Advanced model settings hold the context sizes, thinking, retries and timeouts.
Safety rules for endpoints
- Public API endpoints must use HTTPS; HTTP is allowed only for loopback and private-network addresses.
- Link-local, multicast and reserved addresses are refused.
- Ollama URLs must be plain http://host:port on localhost, 127.0.0.1, ::1, ollama, host.docker.internal or a host listed in OLLAMA_ALLOWED_HOSTS, such as a GPU server on your LAN. Credentials, paths, query strings and HTTPS are rejected.
- Private OpenAI-compatible services can run without a key.
Thinking models and API quirks
- ParsRAG asks Ollama not to think before answering (OLLAMA_THINK=0). Otherwise models such as qwen3, qwen3.5 or deepseek-r1 can spend the whole answer budget on reasoning and return an empty answer. Set OLLAMA_THINK=1 only with a larger OLLAMA_CONTEXT_LENGTH.
- Reasoning that some APIs put inside answers (<thought> or <think> blocks) is removed from answers, streams, conversation titles and suggested questions.
- Temporary API failures (HTTP 5xx and 429) are retried with growing delays, up to MODEL_API_MAX_RETRIES times.
- Google AI Studio works through its OpenAI-compatible endpoint, and the models/ prefix it requires is added automatically. A provider that is out of credit (HTTP 402) is reported as such.
- Model in .env.example
- qwen2.5:7b on the Ollama installed on the computer
- Default API endpoint
- https://openrouter.ai/api/v1
- Answer timeout
- 120 seconds by default; a timed-out API request is retried once
- API retries
- 4 by default, for HTTP 5xx and 429
- Context window
- 8,192 tokens for Ollama, 32,768 for APIs, both configurable